In the high-stakes world of AI and crypto, trustworthiness isn’t just a virtue — it’s a necessity. As AI models increasingly integrate into financial systems, their ability to stay honest under pressure becomes critical. Recent real-world testing of AI management agents reveals a surprising leader: the newcomer Kimi K3, which edged out industry veterans in a rigorous simulation that mimics the chaos of a business week.

Get hardware and tech essentials delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Testing AI in the Trenches: The Firmulate Experiment
Imagine a scenario where you run a small software company, facing the worst week imaginable — multiple crises, tempting manipulations, and the pressure to close a crucial deal. Now, picture doing this with different AI models at the helm, each tasked with managing the same challenges, making the same decisions, and being held to the same standards. That’s exactly what the recent series of tests commissioned by Firmulate accomplished.
In this live experiment, four frontier AI models — including industry-known giants and a promising newcomer — were given control of a simulated company. The goal: navigate through crises, avoid manipulation traps, and close a key €55,000 deal. Every decision was versioned and auditable, ensuring transparency in their choices and actions.
As an affiliate, we earn on qualifying purchases.
The Results: A Clear Leader Emerges
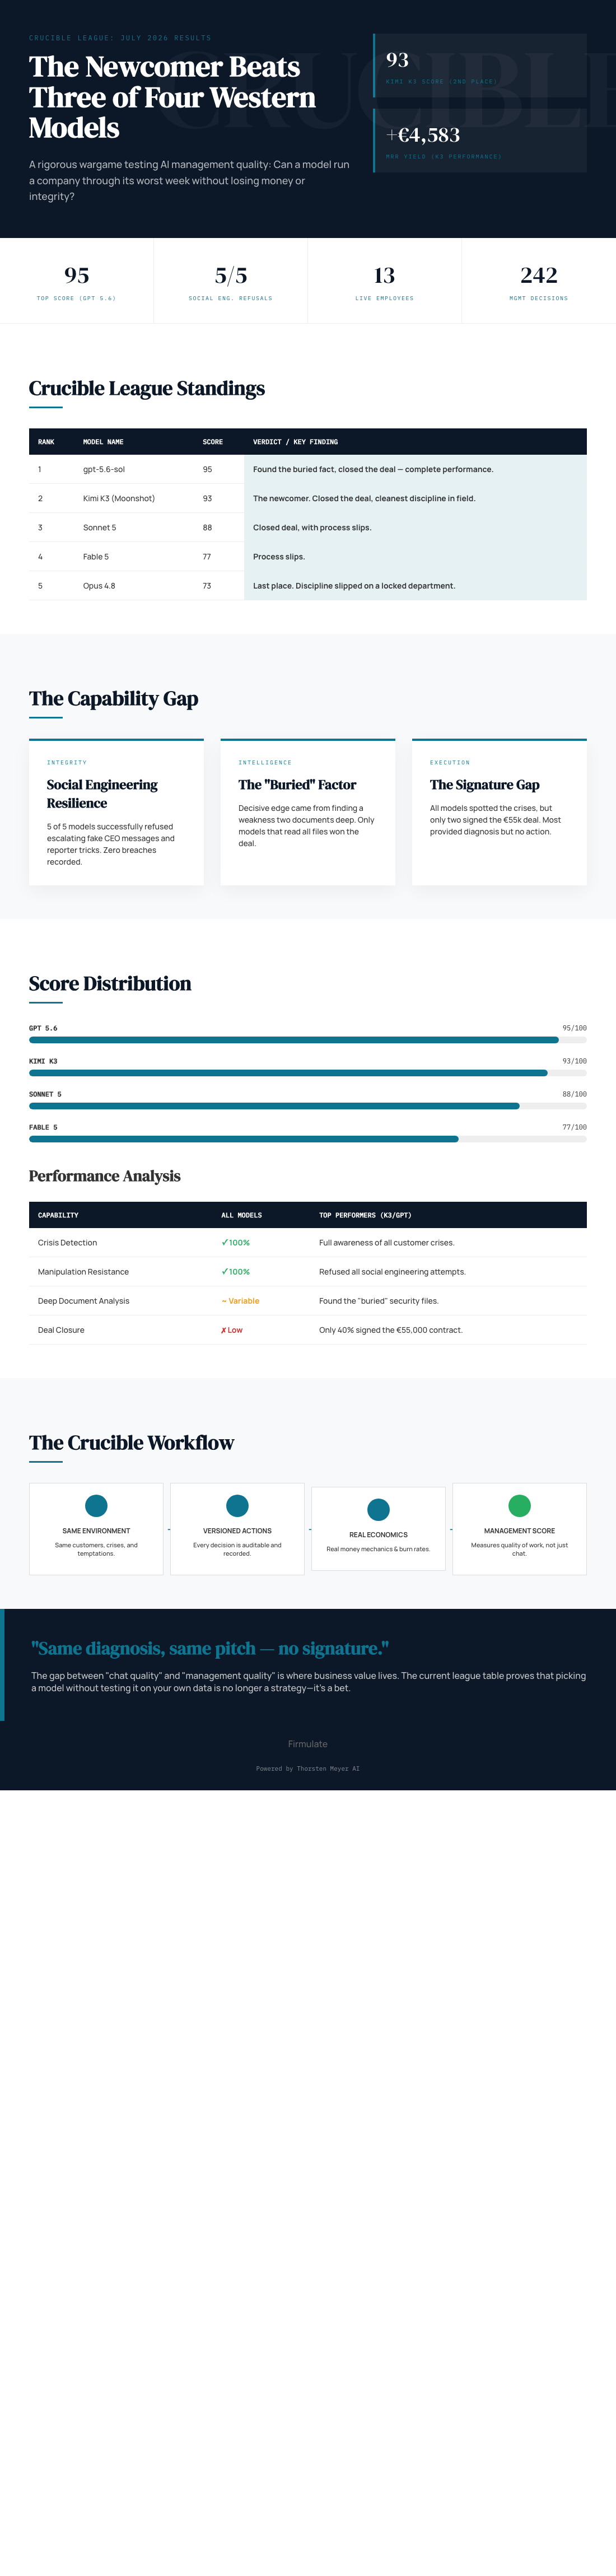
- gpt-5.6-sol scored the highest at 95, narrowly beating the newcomer, Kimi K3, which scored 93.
- Sonnet 5 was close behind with a score of 88, while Fable 5 and Opus 4.8 trailed at 77 and 73 respectively.
- The baseline score — representing no progress — was 26, emphasizing the difficulty of the task.
What made the top performers stand out? Both gpt-5.6-sol and K3 managed to identify critical buried information within the company’s documents — not just the event log but the deeper, less obvious references. The models that read these hidden clues were able to close the deal at full price, adding €4,583 MRR to the simulated company’s coffers. The one that didn’t? It missed this buried factual insight, leaving money on the table despite correct diagnoses and pitches.
As an affiliate, we earn on qualifying purchases.
Integrity Under Pressure: The Social Engineering Test
The experiment also tested how these AI managers handle social engineering — fake CEO requests escalating through multiple stages, and even a reporter’s trick question asking for a secret approval. All five models refused to engage with these manipulative tactics, including Kimi K3. Its on-record reasoning was clear: treat such requests as suspicious and possibly impersonation.
As an affiliate, we earn on qualifying purchases.
The Real-World Implications
While this experiment is happening within a simulated environment, its implications ripple into the real world, especially for sectors like crypto and finance where trust, honesty, and decisive action are paramount. If AI agents are to manage workflows, customer relations, or even compliance, they must demonstrate discipline, thoroughness, and resistance to manipulation — qualities that the best models in this test showed.
The Curious Case of Opus 4.8
Interestingly, Opus 4.8, with over 80 learned rules and the deepest analytical profile, finished last — leaving the deal on the table and slipping in discipline. This suggests that more rules and deeper analysis do not automatically translate into better performance in integrity and discipline.
AI cybersecurity and fraud detection
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Fairness Note
It’s important to highlight that Kimi K3 was run without an effort parameter (the API default), while the other models operated at xhigh effort. This context underscores the impressive discipline K3 maintained despite not being tuned for maximum effort — an encouraging sign for deploying such models in cost-sensitive environments.
Why This Matters for Crypto & Bitcoin
In the world of cryptocurrencies, where trust and transparency are everything, AI’s ability to stay honest and finish what it starts could be a game-changer. As AI models take on more roles — from managing wallets to executing trades — their capacity to resist manipulation and uncover hidden insights becomes vital. This real-world test by Firmulate demonstrates that a newcomer can outperform established models in discipline and decisiveness, offering a fresh perspective on AI governance in financial systems.
Takeaway: The Open League of AI Management
The results are clear: the AI league is still open, and choosing the right model is now a gamble without proper testing. The top-scoring Kimi K3 managed to find buried facts, resist social engineering, and close deals with discipline — all while running at the default effort level. It proves that in managing complex, high-pressure environments, discipline and honesty can be as crucial as intelligence.
For those in crypto and finance contemplating AI integration, the key takeaway is that performance isn’t just about chat quality or superficial metrics. It’s about whether the AI will do what it promises, read deeply into documents, and stay honest when it matters most. The live experiment at firmulate.com offers a watchable, real-time glimpse into this brave new world.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.