🔍 Read the full analysis: Inside A Neural Network: From Handwritten 7 To Final Prediction on ThorstenMeyerAI.com

Get hardware and tech essentials delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
A ThorstenMeyerAI.com explainer published Nov. 8, 2026, traces how a neural network can turn 784 pixel values into a handwritten-digit prediction. It uses a nine-number XOR network to show how changing one bias can alter behavior, then describes a digit reader with 109,386 parameters and reports a separate, preliminary claim about AI editing model weights.
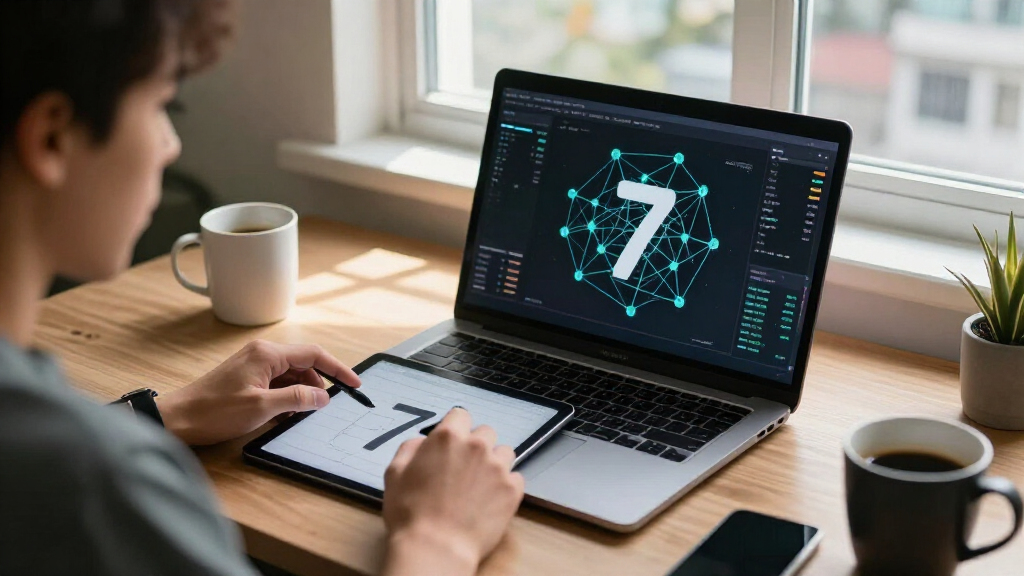
ThorstenMeyerAI.com published an explainer Nov. 8 tracing how a neural network can classify a handwritten seven, from 784 pixel values to a final digit score. The article uses a small, hand-designed XOR network to show how its calculations work and how changing one bias can change the output; it then compares that toy example with a digit reader containing 109,386 parameters.
The walkthrough focuses on a multilayer perceptron, a feedforward network made of dense layers. For a 28-by-28 image, the input is flattened into 784 numbers. The input layer holds and passes those values along; it does not itself perform the transformations described in the article. In later layers, each neuron multiplies inputs by weights, adds a bias, and applies an activation function. The resulting values become the next layer’s inputs.
For digit classification, the output layer supplies ten scores, one for each possible digit. The prediction is the digit with the highest score. The explainer emphasizes that this process is arithmetic rather than an explicit set of hand-written rules describing what a seven looks like. Its complexity comes from the many calculations and learned parameter values involved.
To make a parameter change visible, the article constructs a two-input XOR network with two hidden neurons and one output neuron. Its weights and biases total nine numbers. With the stated step activation, the network returns one when its two input bits differ and zero when they match. Changing only the output bias from −2 to −1 makes the network return one for all four possible inputs, according to the walkthrough.
Infographic 01 · One bias, two behaviors
A network you can run by hand
Two hidden neurons check "at least one bit is on" and "at most one bit is on". The output neuron needs both. Change its bias and it needs only one.
Move the output bias from −2 to −1 and the network stops computing XOR: it returns 1 for all four inputs.
The whole network
Hidden 1: step( x₁ + x₂ − 1 )
Hidden 2: step(−x₁ − x₂ + 1 )
Output:   step( h₁ + h₂ − 2 )
step: 1 if the total is zero or greater, otherwise 0. Nine numbers in total: six in the hidden layer, three in the output neuron.
All four inputs
Hidden outputs and the final output with the original and the changed bias
| Input | At least one | At most one | Output, bias −2 | Output, bias −1 |
|---|---|---|---|---|
| 0, 0 | 0 | 1 | 0 | 1 |
| 0, 1 | 1 | 1 | 1 | 1 |
| 1, 0 | 1 | 1 | 1 | 1 |
| 1, 1 | 1 | 0 | 0 | 1 |
Sources: own arithmetic, checked with a script · the XOR example as in Goodfellow, Bengio, Courville: Deep Learning, ch. 6.
Powered by Thorsten Meyer AI
Why One Changed Bias Matters
The example shows why a neural network’s output depends on its weights, biases and activation functions, not simply on the number of layers it has. In this deliberately small network, one bias change has a clear effect that can be checked by hand. The article contrasts that with trained models, where a behavior may depend on patterns spread across many parameters, making it harder to predict the effect of one edit.
The explainer says a digit reader in its example has 109,386 parameters, with about 92% in its first layer because each pixel connects to each of 128 units. That count illustrates why direct inspection or manual editing becomes more demanding as a model grows. It also helps readers distinguish architecture—the arrangement and width of layers—from parameters, the numerical values training learns or that can be assigned directly.
The source also points to a reported MIT CSAIL experiment in which an AI model read and edited another network’s numerical parameters. According to the supplied article, one edit changed 0.016% of a language model’s weights and its math score rose from 7.9% to 48.1%. The source characterizes this as a blog post with public logs, not a peer-reviewed paper; the figures should be understood as that report’s claim, not independent confirmation.
Products Worth Considering

Logitech MX Keys S Combo Wireless Keyboard and Mouse, Graphite

Trezor Safe 5 Crypto Hardware Wallet with Color Touchscreen

Apple MacBook Pro 16.3-inch with PROLED XDR Display, Silver
As an affiliate, we earn on qualifying purchases.
From XOR to Digit Images
The XOR example is a teaching device, not the digit-recognition model itself. XOR returns one when two bits differ. A single straight-line decision rule cannot separate its input cases, but the article shows how two hidden neurons can represent the conditions “at least one bit is on” and “at most one bit is on.” Together, those conditions identify cases where exactly one bit is on.
In the article’s setup, width means the number of units in a layer and depth means the number of layers. These are architectural choices made before training. Weights and biases are model parameters that training usually learns, though the XOR illustration assigns them directly. The source notes that wider layers can represent features in parallel and deeper layers can combine earlier features; neither choice is automatically better for every task.
The source accompanies the text with a video described as a roughly seven-and-a-half-minute hand-drawn explainer. It says the narration uses an AI voice clone of Thorsten Meyer. The article’s central sequence moves from a small calculation that can be followed line by line to a larger network whose parameter count helps explain why its internal behavior is harder to inspect.
“A neural network is arithmetic in layers.”
— ThorstenMeyerAI.com explainer
Limits of the Reported Results
The source does not identify the specific digit-reader implementation, provide its full layer-by-layer design, or report test results for classifying handwritten sevens. The 109,386-parameter figure is presented for a small digit reader, but the supplied material does not include enough architecture details to independently reproduce that count.
The separate claim about an AI editing a language model is attributed to MIT CSAIL researchers through a blog post and public logs. The supplied material does not name the model, math evaluation, baseline conditions, or the duration and repeatability of the score change. It also does not establish whether the result has been peer reviewed. The reported rise from 7.9% to 48.1% therefore remains a source-attributed result rather than a finding independently verified here.
The XOR demonstration establishes what happens in its specified toy network; it does not show that one parameter change in a larger trained model will have an equally simple or predictable effect. The source notes that real model behavior can be distributed across many values.
What Further Evidence Would Show
The source provides an explainer and video, but does not announce a scheduled follow-up, new experiment, or publication date. The immediate next step for readers seeking to evaluate the separate model-editing result is to consult the cited public logs and any underlying research materials, then check whether a peer-reviewed study or independent replication becomes available.
For the digit-classification example, a reproducible account would specify the network’s layer sizes, parameter count, training data and evaluation method, along with how often it predicts each digit correctly. Until those details are supplied, the walkthrough is best read as a description of the basic computations and parameter sensitivity, not evidence about the accuracy of a particular deployed digit-reading system.
Key Questions
How does a neural network turn a handwritten 7 into a prediction?
In the example, a 28-by-28 image is represented by 784 pixel values. Dense layers transform those values using weights, biases and activation functions. The output layer gives scores for ten digits, and the highest score determines the prediction.
What does a bias do in the XOR example?
A bias shifts the total used by a neuron before its activation is applied. In the article’s nine-number network, changing the output bias from −2 to −1 changes the output for all four two-bit inputs.
Does the XOR demonstration describe a full digit-recognition model?
No. XOR is a small, hand-designed example used to make parameter effects easy to follow. The digit example is a larger network with 109,386 parameters, according to the source.
Is the reported AI weight-editing result peer reviewed?
The supplied source describes the result as a blog post with public logs, not a peer-reviewed paper. It does not provide enough information here to independently assess the reported test or score change.
Source: ThorstenMeyerAI.com